Conformer block
A transformer block with a convolution module inside. Attention for global context, convs for local acoustic detail.
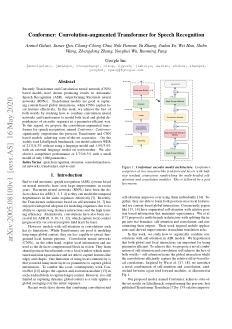 Introduced inMay 2020Conformer: Convolution-augmented Transformer for Speech Recognition
The Conformer sandwiches a depthwise-convolution module between attention and feed-forward layers (in a macaron FFN-attention-conv-FFN pattern), usually with relative position encoding in the attention. Convolutions capture local spectral patterns that pure attention handles poorly, which made Conformers the dominant speech-encoder architecture (NVIDIA’s FastConformer here).
Adoption over time
Share of new models that have included Conformer blocks over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 google/gemma-4-E4B-itany-to-any · ↓ 4.4M · ♡ 2kOpen in visualizer

 ResembleAI/chatterboxtext-to-speech · ↓ 1.8M · ♡ 2kOpen in visualizer

 nvidia/nemotron-3.5-asr-streaming-0.6bautomatic-speech-recognition · ↓ 752k · ♡ 1kOpen in visualizer
 nvidia/parakeet-tdt-0.6b-v3automatic-speech-recognition · ↓ 577k · ♡ 1kOpen in visualizer
 nvidia/nemotron-speech-streaming-en-0.6bautomatic-speech-recognition · ↓ 419k · ♡ 624Open in visualizer

 ai-sage/GigaAM-v3automatic-speech-recognition · ↓ 414k · ♡ 163Open in visualizer

 facebook/seamless-m4t-v2-largeautomatic-speech-recognition · ↓ 306k · ♡ 1kOpen in visualizer

 ibm-granite/granite-speech-4.1-2bautomatic-speech-recognition · ↓ 236k · ♡ 162Open in visualizer

 CohereLabs/cohere-transcribe-03-2026automatic-speech-recognition · ↓ 207k · ♡ 1kOpen in visualizer
 google/gemma-3n-E2B-itimage-text-to-text · ↓ 171k · ♡ 327Open in visualizer
 ibm-granite/granite-speech-4.1-2b-plusautomatic-speech-recognition · ↓ 132k · ♡ 92Open in visualizer
 nvidia/canary-1b-v2automatic-speech-recognition · ↓ 47k · ♡ 423Open in visualizer
View 58 catalog matches for Conformer block →
Related concepts
hfviewer renders the full architecture of 6,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →