Vision encoder (ViT)
A transformer over image patches that turns pictures into a sequence of visual embeddings.
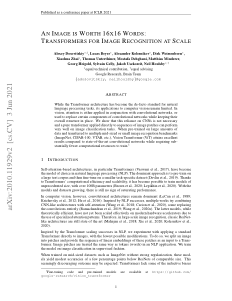 Introduced inOct 2020An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
The vision tower of a multimodal model is usually a ViT-family encoder (SigLIP and CLIP variants dominate) pretrained on image-text pairs. It converts patch embeddings into contextualized visual features that a projector then aligns with the language model’s embedding space. Multimodal capability lives or dies by this component and how it was pretrained.
Adoption over time
Share of new models that have included a vision encoder over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 Qwen/Qwen3.6-35B-A3B-FP8image-text-to-text · ↓ 5.3M · ♡ 412Open in visualizer
 Qwen/Qwen3.6-35B-A3Bimage-text-to-text · ↓ 3.4M · ♡ 3kOpen in visualizer

 microsoft/TRELLIS-image-largeimage-to-3d · ↓ 2.7M · ♡ 682Open in visualizer

 google/gemma-3-4b-itimage-text-to-text · ↓ 1.8M · ♡ 2kOpen in visualizer

 llava-hf/llava-1.5-7b-hfimage-text-to-text · ↓ 1.7M · ♡ 375Open in visualizer
 google/medgemma-4b-itimage-text-to-text · ↓ 1.1M · ♡ 1kOpen in visualizer

 nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-FP8any-to-any · ↓ 959k · ♡ 63Open in visualizer
 Qwen/Qwen3-VL-Reranker-2Btext-ranking · ↓ 899k · ♡ 221Open in visualizer

 black-forest-labs/FLUX.1-devtext-to-image · ↓ 751k · ♡ 15kOpen in visualizer

 Infomaniak-AI/vllm-translategemma-4b-itimage-text-to-text · ↓ 746k · ♡ 14Open in visualizer

 ISTA-DASLab/gemma-3-27b-it-GPTQ-4b-128gimage-text-to-text · ↓ 714k · ♡ 45Open in visualizer
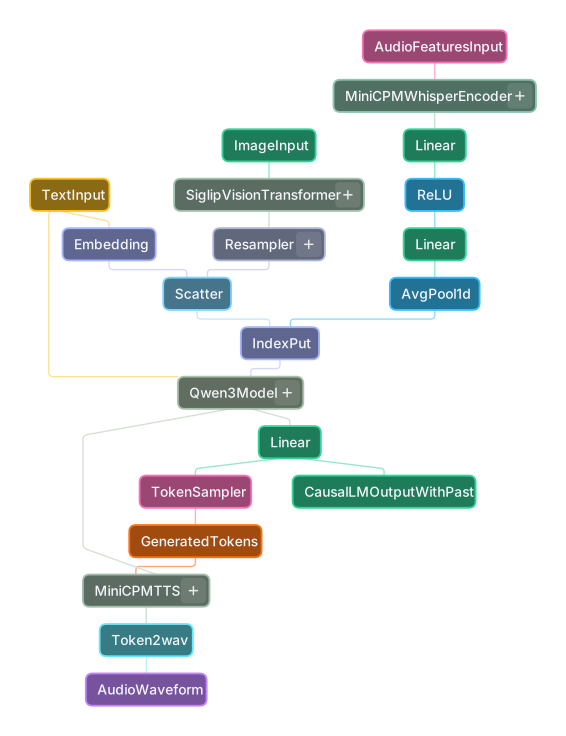
 openbmb/MiniCPM-o-4_5any-to-any · ↓ 683k · ♡ 1kOpen in visualizer
View 260 catalog matches for Vision encoder (ViT) →
Related concepts
hfviewer renders the full architecture of 6,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →