Patch embedding
Slices the image into fixed-size patches and projects each one into a token. How pixels become a sequence.
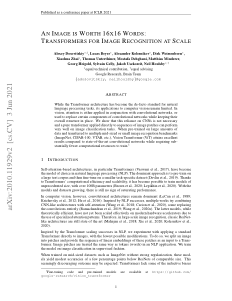 Introduced inOct 2020An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Vision transformers do not see pixels; they see patches. The image is cut into a grid of fixed-size squares, each flattened and linearly projected into an embedding. One ‘visual token’ per patch. From that point on the vision encoder is just a transformer over a sequence, which is exactly why the same machinery works for text and images.
Adoption over time
Share of new models that have included patch embedding over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 Comfy-Org/MiniMax-H3↓ 23.3M · ♡ 2kOpen in visualizer

 openai/clip-vit-base-patch32zero-shot-image-classification · ↓ 21.9M · ♡ 2kOpen in visualizer

 Qwen/Qwen3-VL-8B-Instructimage-text-to-text · ↓ 19.7M · ♡ 1kOpen in visualizer

 google/gemma-4-26B-A4B-itimage-text-to-text · ↓ 13.1M · ♡ 2kOpen in visualizer
 Qwen/Qwen3.5-9Bimage-text-to-text · ↓ 9.2M · ♡ 2kOpen in visualizer
 google/gemma-4-31B-itimage-text-to-text · ↓ 9.0M · ♡ 4kOpen in visualizer

 autogluon/chronos-2time-series-forecasting · ↓ 8.7M · ♡ 72Open in visualizer
 openai/clip-vit-large-patch14zero-shot-image-classification · ↓ 8.1M · ♡ 2kOpen in visualizer

 nvidia/Qwen3.6-35B-A3B-NVFP4text-generation · ↓ 8.0M · ♡ 628Open in visualizer
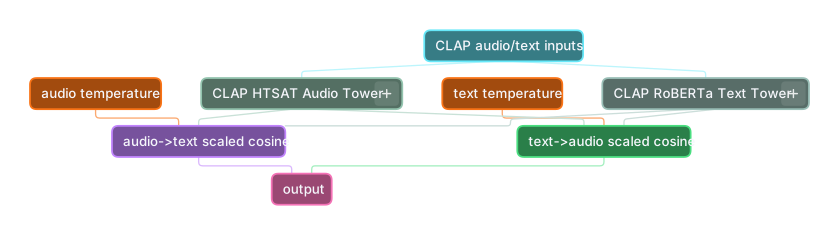
 laion/clap-htsat-fusedaudio-classification · ↓ 7.8M · ♡ 149Open in visualizer

 amazon/chronos-bolt-smalltime-series-forecasting · ↓ 7.7M · ♡ 49Open in visualizer
 Qwen/Qwen3.8-27Bimage-text-to-text · ↓ 7.3M · ♡ 16kOpen in visualizer
View 1,912 catalog matches for Patch embedding →
Related concepts
hfviewer renders the full architecture of 6,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →