VAE (latent autoencoder)
Compresses images into a small latent space where diffusion actually happens, then decodes the result back to pixels.
 Introduced inDec 2013Auto-Encoding Variational Bayes
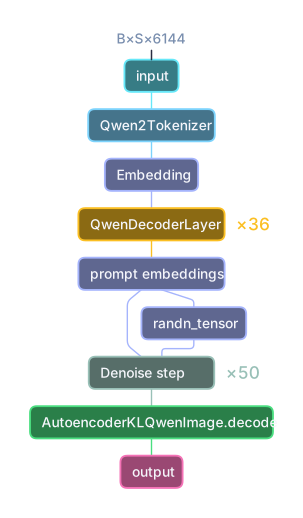
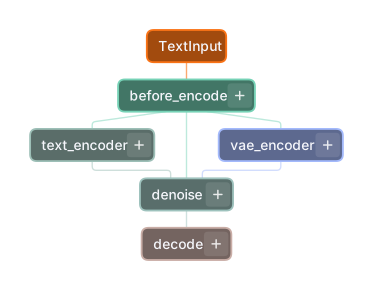
Latent diffusion models never diffuse pixels directly. A variational autoencoder first compresses the image into a compact latent tensor, typically 8× smaller per side (16× in newer models such as Qwen-Image 2.1), the diffusion process denoises in that space, and the VAE decoder renders the final latent back into pixels. This is the trick that made high-resolution diffusion affordable, and it is why generation graphs end with a VAE decode stage.
Adoption over time
Share of new models that have included a VAE over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 Comfy-Org/MiniMax-H3↓ 23.3M · ♡ 2kOpen in visualizer
 Comfy-Org/Krea-2↓ 9.8M · ♡ 573Open in visualizer
 Comfy-Org/Qwen-Image-2.1↓ 6.0MOpen in visualizer
 MiniMaxAI/MiniMax-H3image-text-to-video · ↓ 4.1M · ♡ 6kOpen in visualizer

 stabilityai/stable-diffusion-xl-base-1.0text-to-image · ↓ 3.1M · ♡ 8kOpen in visualizer

 microsoft/TRELLIS.2-4Bimage-to-3d · ↓ 1.9M · ♡ 1kOpen in visualizer

 stable-diffusion-v1-5/stable-diffusion-v1-5text-to-image · ↓ 1.8M · ♡ 1kOpen in visualizer

 nvidia/Cosmos3-Edge↓ 1.5M · ♡ 208Open in visualizer

 circlestone-labs/Anima↓ 1.2M · ♡ 2kOpen in visualizer
 stabilityai/sdxl-turbotext-to-image · ↓ 886k · ♡ 3kOpen in visualizer

 Lightricks/LTX-Videoimage-to-video · ↓ 769k · ♡ 2kOpen in visualizer

 black-forest-labs/FLUX.1-devtext-to-image · ↓ 751k · ♡ 15kOpen in visualizer
View 362 catalog matches for VAE (latent autoencoder) →
Related concepts
hfviewer renders the full architecture of 6,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →