DiT block (diffusion transformer)
A transformer block operating on image-latent tokens, modulated by the diffusion timestep.
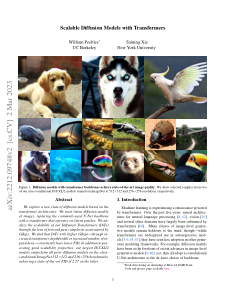 Introduced inDec 2022Scalable Diffusion Models with Transformers
Diffusion transformers replace the classic U-Net with a stack of transformer blocks over patchified latent tokens. Each block is conditioned on the timestep (and prompt) through adaptive layer-norm modulation. The timestep embedding shifts and scales activations inside every block. DiTs scale more predictably than U-Nets and power most recent image and video generators.
Adoption over time
Share of new models that have included DiT blocks over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 Comfy-Org/MiniMax-H3↓ 23.3M · ♡ 2kOpen in visualizer
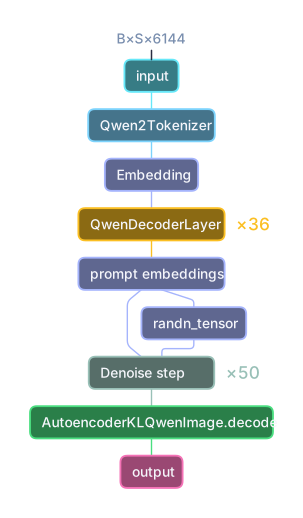 Comfy-Org/Krea-2↓ 9.8M · ♡ 573Open in visualizer

 coqui/XTTS-v2text-to-speech · ↓ 7.2M · ♡ 4kOpen in visualizer
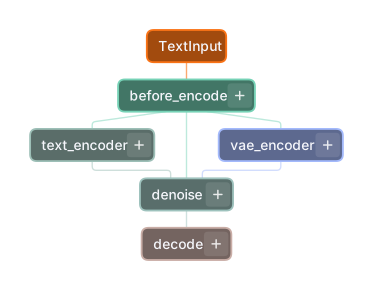
 MiniMaxAI/MiniMax-H3image-text-to-video · ↓ 4.1M · ♡ 6kOpen in visualizer

 stabilityai/stable-diffusion-xl-base-1.0text-to-image · ↓ 3.1M · ♡ 8kOpen in visualizer

 ResembleAI/chatterboxtext-to-speech · ↓ 1.8M · ♡ 2kOpen in visualizer

 stable-diffusion-v1-5/stable-diffusion-v1-5text-to-image · ↓ 1.8M · ♡ 1kOpen in visualizer

 Lightricks/LTX-2.5image-to-video · ↓ 1.6M · ♡ 5kOpen in visualizer

 nvidia/Cosmos3-Edge↓ 1.5M · ♡ 208Open in visualizer
 Lightricks/LTX-2.3image-to-video · ↓ 1.1M · ♡ 2kOpen in visualizer

 unsloth/MiniMax-H3-GGUFimage-text-to-video · ↓ 979k · ♡ 302Open in visualizer
 stabilityai/sdxl-turbotext-to-image · ↓ 886k · ♡ 3kOpen in visualizer
View 420 catalog matches for DiT block (diffusion transformer) →
Related concepts
hfviewer renders the full architecture of 6,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →