Linear attention (gated DeltaNet)
Replaces the attention matrix with a fixed-size recurrent state. Cost stays constant per token, no KV cache growth.
 Introduced inJun 2020Transformers are RNNs: Fast Autoregressive Transformers with Linear Attention
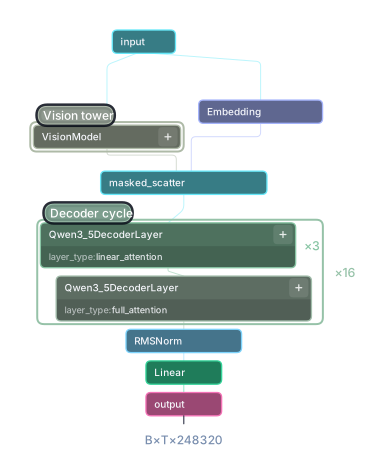
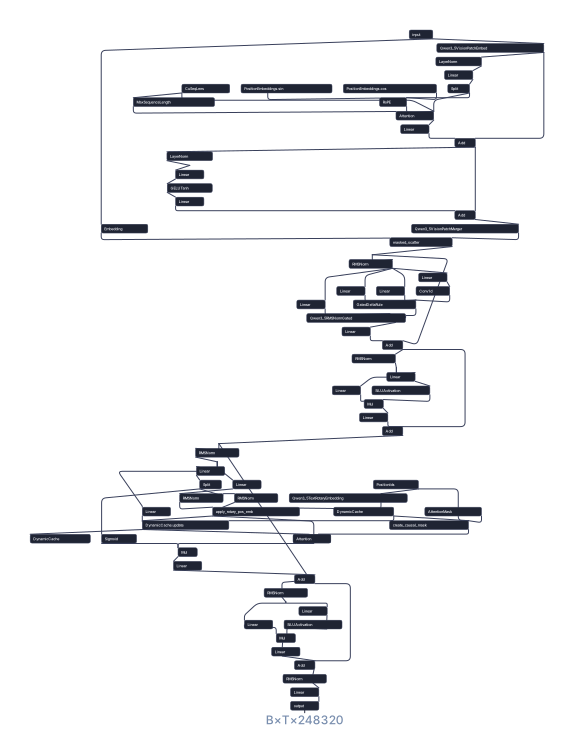
Linear attention keeps a compact running state that is updated once per token (here with the gated delta rule: the state is selectively decayed and rewritten), so generation cost does not grow with context length and there is no per-token KV cache. Qwen3.5-style hybrids use linear attention in most layers and keep periodic full-attention layers for precise long-range recall. The best of both worlds for long contexts.
Adoption over time
Share of new models that have included linear attention over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 Qwen/Qwen3.6-35B-A3B-FP8image-text-to-text · ↓ 9.5M · ♡ 412Open in visualizer
 Qwen/Qwen3.5-9Bimage-text-to-text · ↓ 9.2M · ♡ 2kOpen in visualizer

 nvidia/Qwen3.6-35B-A3B-NVFP4text-generation · ↓ 8.0M · ♡ 628Open in visualizer
 Qwen/Qwen3.8-27Bimage-text-to-text · ↓ 7.3M · ♡ 16kOpen in visualizer
 Qwen/Qwen3.8-27B-FP8image-text-to-text · ↓ 6.9M · ♡ 846Open in visualizer
 Qwen/Qwen3.5-4Bimage-text-to-text · ↓ 6.8M · ♡ 943Open in visualizer
 Qwen/Qwen3.6-27B-FP8image-text-to-text · ↓ 5.6M · ♡ 357Open in visualizer
 Qwen/Qwen3.5-2Bimage-text-to-text · ↓ 4.8M · ♡ 408Open in visualizer
 lmstudio-community/Qwen3.8-27B-MLX-4bitimage-text-to-text · ↓ 4.7M · ♡ 73Open in visualizer
 lmstudio-community/Qwen3.8-27B-MLX-8bitimage-text-to-text · ↓ 4.5M · ♡ 28Open in visualizer
 Qwen/Qwen3.6-27Bimage-text-to-text · ↓ 3.5M · ♡ 2kOpen in visualizer

 unsloth/Qwen3.8-27B-NVFP4↓ 3.3M · ♡ 464Open in visualizer
View 753 catalog matches for Linear attention (gated DeltaNet) →
Related concepts
hfviewer renders the full architecture of 5,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →