Short convolution block
A gated, depthwise causal convolution mixes only a few neighboring tokens. A very cheap substitute for attention.
 Goes back toDec 2022Hungry Hungry Hippos: Towards Language Modeling with State Space Models
Some hybrid models (LFM2, Nemotron-H) replace most attention layers with short causal convolutions: each position mixes information from just the last few tokens through a depthwise conv, with multiplicative gates deciding what passes through. It is dramatically cheaper than attention and surprisingly capable for local patterns; the few remaining attention layers supply global context.
Adoption over time
Share of new models that have included short convolution blocks over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 nvidia/NVIDIA-Nemotron-3-Nano-4B-BF16text-generation · ↓ 3.5M · ♡ 121Open in visualizer

 moonshotai/Kimi-K3image-text-to-text · ↓ 2.0M · ♡ 11kOpen in visualizer
 nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-BF16text-generation · ↓ 1.3M · ♡ 426Open in visualizer
 nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4text-generation · ↓ 1.0M · ♡ 431Open in visualizer
 nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-NVFP4text-generation · ↓ 827k · ♡ 180Open in visualizer
 nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-NVFP4text-generation · ↓ 744k · ♡ 436Open in visualizer
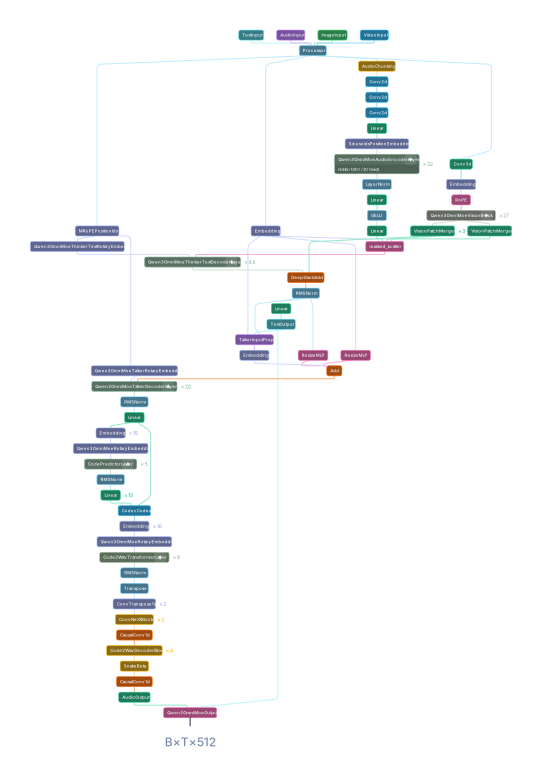
 Qwen/Qwen3-Omni-30B-A3B-Instructany-to-any · ↓ 680k · ♡ 1kOpen in visualizer
 nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-BF16text-generation · ↓ 666k · ♡ 823Open in visualizer
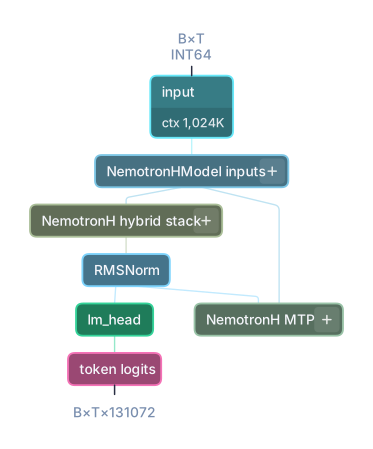 nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16text-generation · ↓ 570k · ♡ 218Open in visualizer
 nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-FP8text-generation · ↓ 409k · ♡ 360Open in visualizer
 nvidia/NVIDIA-Nemotron-Nano-9B-v2text-generation · ↓ 383k · ♡ 519Open in visualizer
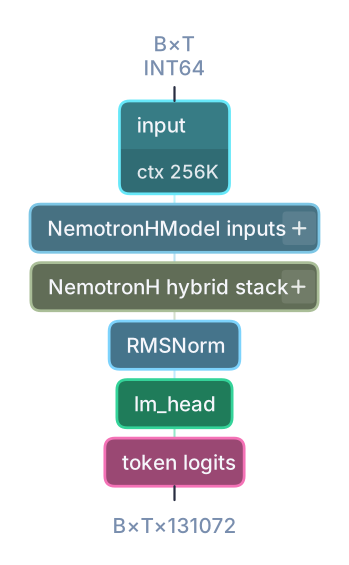
 RedHatAI/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-FP8text-generation · ↓ 357k · ♡ 2Open in visualizer
View 85 catalog matches for Short convolution block →
Related concepts
hfviewer renders the full architecture of 6,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →