Attention sink
A learned ‘nowhere’ slot lets a head cleanly attend to nothing instead of smearing weight over random tokens.
 Introduced inSep 2023Efficient Streaming Language Models with Attention Sinks
Softmax forces attention weights to sum to one, so a head that has nothing relevant to look at must still put its weight somewhere. Often degrading quality. An attention sink adds a learned logit (or a pinned first token) that absorbs that leftover probability. gpt-oss bakes per-head sink parameters into every attention layer; the same idea is why streaming-inference tricks keep the first tokens around.
Adoption over time
Share of new models that have included attention sinks over time.
See it in real models
Open any of these on hfviewer to find this block in the interactive architecture graph.

 deepseek-ai/DeepSeek-V4-Flashtext-generation · ↓ 1.6M · ♡ 2kOpen in visualizer
 deepseek-ai/DeepSeek-V4-Flash-DSparktext-generation · ↓ 1.0M · ♡ 281Open in visualizer
 deepseek-ai/DeepSeek-V4-Protext-generation · ↓ 569k · ♡ 6kOpen in visualizer

 sgl-project/DeepSeek-V4-Flash-FP8↓ 348k · ♡ 15Open in visualizer
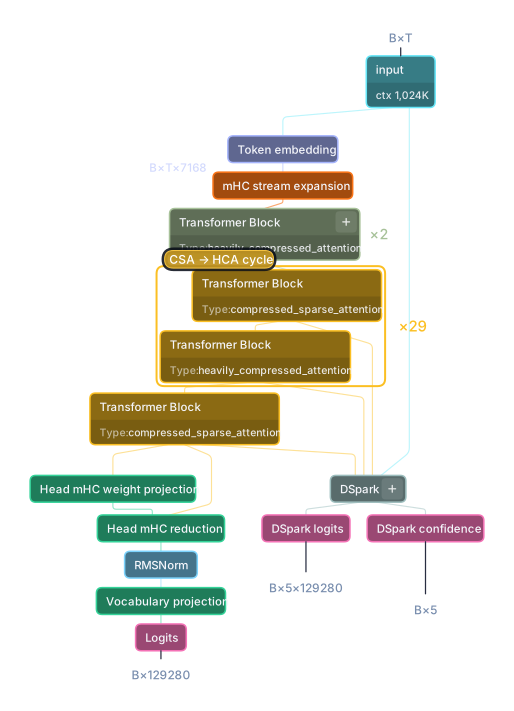 deepseek-ai/DeepSeek-V4-Pro-0813text-generation · ↓ 160k · ♡ 842Open in visualizer

 0xSero/deepseek-v4-flash-0731-sparktext-generation · ↓ 144k · ♡ 50Open in visualizer

 MJPansa/DeepSeek-V4-Flash-0731-NVFP4text-generation · ↓ 125k · ♡ 18Open in visualizer

 AtlasCloud/DeepSeek-V4-Flash-0731-FP8-DSpark↓ 112k · ♡ 5Open in visualizer
 AtlasCloud/DeepSeek-V4-Flash-Vision-Exp-FP8-DSparkimage-text-to-text · ↓ 29kOpen in visualizer

 apetersson/DeepSeek-V4-Flash-0731-Abliterated-FP8text-generation · ↓ 17k · ♡ 38Open in visualizer

 nex-agi/Nex-N2.5-Maxtext-generation · ↓ 12k · ♡ 56Open in visualizer
 sgl-project/DeepSeek-V4-Pro-FP8↓ 9k · ♡ 13Open in visualizer
View 42 catalog matches for Attention sink →
Related concepts
hfviewer renders the full architecture of 6,700+ Hugging Face models as interactive graphs. Hover any block to see what it does, with this model’s real numbers.
Browse all model graphs →